



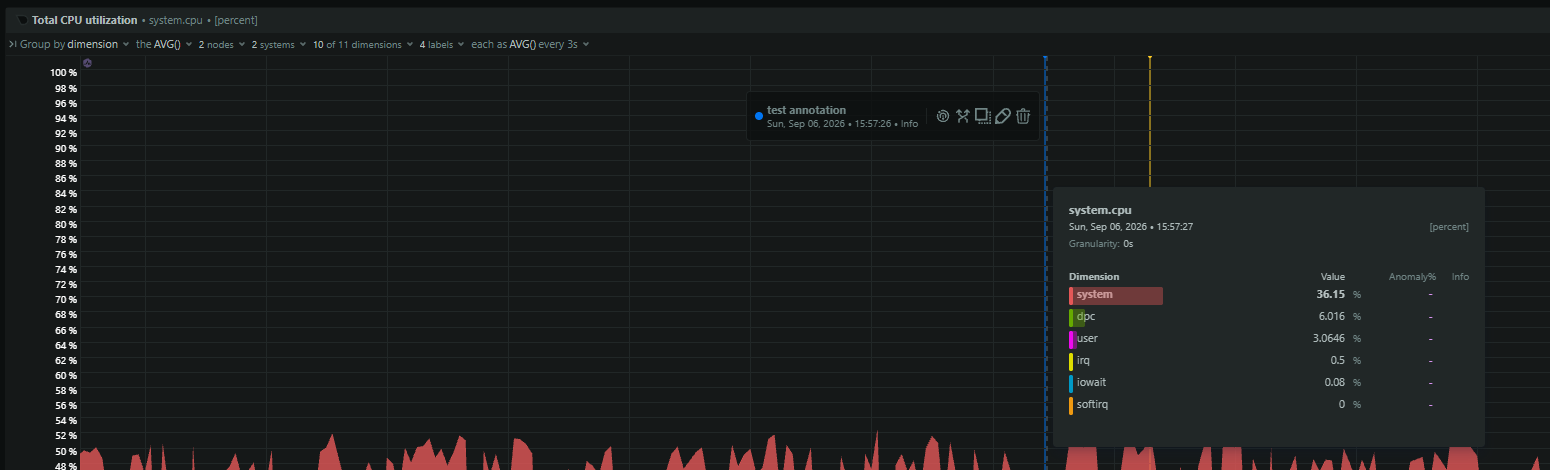


You have lived it, no? When production is down, and you have that chart that says something really strange and peculiar, and nobody knows who did it or when.
Production is bleeding. There is a spike on screen. And the chart answers everything except the question you actually have: who built this panel, what did they mean by it, and are they still here?
Ask the room and you get what one sysadmin got: “When I asked who is actually monitoring the dashboard… there was silence.” (r/sysadmin) Ask the industry and you get the pattern one SRE described: the two people who understood the dashboards left the company, and the monitoring stack went with them. Another SRE, from a 1,000-person company: “the 2 guys looking after the LGTM stack left…” (r/sre) And after the page fires, the clock everyone knows starts: “We’d lose 10-15 minutes just getting oriented.” (r/sre)
This is not a skills gap. It is the design.
It is 2026 and AI builds dashboards now. So ask who made that weird panel and, increasingly, the honest answer is: “Claude.”
Great. Now ask Claude why it built it. Ask at 3 a.m., alone.
Let me explain why all this is wrong
Your infrastructure is not exotic. I run APIs, you run APIs. I run databases, you run databases. We all run Linux or Windows servers, or a fleet of IoT devices, and we all have deployments, workloads, latencies, errors, and saturations. We are not that different.
But every one of us goes through the same ritual: building the same server monitoring dashboard, by hand, for infrastructure that is basically the same. “Tailored to your needs” sounds cool right up until the bill arrives, and the bill is paid in labor, skills, and maintenance, and in practice it never pays off.
In their words:
- “I just spent 4 hours making a dashboard for three new services… 4 hours of mouse dragging, more time than it took me to add code for those metrics. I feel like I’m falling to Excel Power User performance level.” (r/devops). And the reply from the other side, conceding everything: “Dashboards we build can take up to two weeks.”
- “Add to Grafana Cloud around a hundred hours of manual labour to actually set up and creat the dashboards.” (r/devops). The typo is theirs. The hours are real.
- “an endless 2-3 year cycle between the dashboards being cleaned up and then falling back into disrepair… 50,000 dashboards, some good, lots awful.” (r/sre). And the killer detail: the work funnels to “one or two people who have the right interest and skill” because “it’s just not considered to be a real job.”
The survey data says the same thing without the profanity:
- The median share of work spent on toil rose to 30% in 2025, the first increase in five years (Catchpoint SRE Report).
- 78% of developers spend 30% or more of their time on manual toil (Harness State of Software Delivery).
- 73% of organizations had outages linked to ignored or suppressed alerts (Splunk State of Observability).
- High-impact outages cost a median $2M per hour, $76M per year (New Relic Observability Forecast). The average incident: ~$800K, nearly 3 hours to resolve (PagerDuty).
- And the average Grafana user juggles 16 data sources across 8 tools (Grafana’s own survey).
One caveat, because you’ll check: nobody publishes “dashboards added per incident” as a statistic. Nobody needs to. It’s written into the process. PagerDuty’s own postmortem guide says it plainly: “If there is not monitoring for this service or behavior, make building monitoring an action item for this postmortem.” Every incident adds monitoring. No process ever removes any. Engineers describe the result the same way everywhere: every retro adds a panel “so we can see it next time”, and nobody deletes it when it goes flat. That’s where the panel in the first paragraph came from: an incident, at 2 a.m., built by someone who has since left. What does get measured is the cost: Grafana’s 2026 survey ranks complexity and overhead as the #1 observability concern, ahead of noise and cost. We put numbers on our side of it in the hidden costs of monitoring.
I rejected all of this
When we built Netdata, I rejected all of it. No way. I’ve been making this case since 2023 (the future of monitoring is automated and opinionated); what changed is that the alternative is now complete. Netdata is built for operators, to save time rather than waste it.
And it turned out to be simple: attach just 5 tags to every metric and the dashboard becomes an algorithmic dashboard, with each chart a cube you can slice and dice with a click.
Magic?
No! Simplicity!
The five questions
Every metric collected must answer five questions. That’s the whole thing. Five decisions, made once, at the collector, in place of a query language or a dashboard editor:
1. Which thing does this metric monitor? (Instance)
Is it the PostgreSQL server? A database in it? A table in that database? An index of that table? It has to be exactly one. You cannot chart them all together, so it cannot be all of them at once.
The rest of the industry doesn’t even have a name for this. A metric carries a bag of labels (server, database, table, index), and nothing says which of them identify the thing it measures. So every dashboard rediscovers it, panel by panel, with sum by (...) queries and recording rules that roll indexes up to tables and tables up to databases.
We call it an Instance — a Component — and it is decided once, at the collector. Instances have labels: a name, a serial number, a color, or whatever is statically assigned to this instance to identify it.
2. Where does this component belong? (Family)
This is a path. Think of it like a filesystem: where do I find this thing? We call it the family, and it is your table of contents.
3. How many different sensors do we monitor on it? (Context)
These are its contexts, and they define the units of measurement. If the component is a car, we monitor speed, torque, acceleration, tire pressure, rpm, temperature, and each of those is a context.
4. How many measurements does each sensor have? (Dimension)
These are the dimensions. The car measures inside and outside temperature. A disk has reads and writes.
5. Where do we get these readings from? (Node)
This is the node.
Nodes, Instances, Dimensions, Labels = the NIDL Framework.
Well, ok, there are also Contexts and Families, but NIDL is cooler and kind of related (like, needle in the haystack :)
And the NIDL Framework solves dashboard design forever. You hardcode these five items into every metric collected and you get 100% fully automated, algorithmically generated dashboards, for your whole infrastructure.
It’s in our docs, and it is the sentence the entire industry refuses to write: “Metric design IS dashboard design. The choices made during data collection directly determine the usability of the automatically generated dashboards. There is no separate dashboard configuration step.”
The industry says dashboards are something you build. We say dashboard design happens at the collector, once, declaratively, and the dashboard is an algorithm that runs itself.
What an automatic server monitoring dashboard gives you
Slicing (filtering) and dicing (re-grouping) by nodes, instances, dimensions, labels, with a click. Every chart is a cube. Pivot the same data any way you want. There’s no query to write, no panel editor, and no saving a “dashboard copy (2) final FINAL”.
A fully automated table of contents, built from families, the path where things are found. Your monitoring has a ToC. Try finding the one for your 200 Grafana dashboards.
Zero query languages to learn. There is no query to write, so no AI writes one for you either.
Zero dashboards to build by hand. When a new node appears, its dashboard already exists. When a new exporter is scraped, its dashboard already exists. There is nothing to build, so there is nothing to maintain, nothing to rot, nothing to lose in a re-org.
And on every metric, anomaly detection is enabled by default: 18 consensus ML models per metric that train locally and flag deviations from the first minutes. You didn’t configure that either. Knowing which of the 500 signals matters at 3 a.m. was never supposed to be your side job.
So, about that “Claude” answer
AI really does build dashboards now. Grafana Assistant writes panels from natural language, Datadog’s Bits agents “generate dashboards”, New Relic’s AI writes your NRQL. The industry’s 2026 answer to the dashboard tax is: pay it faster.
Generation is free now. Verification is your problem. As one engineer put it: “Just because you can see the dashboard rendering some charts does not necessarily mean it is correct.” (r/PrometheusMonitoring) And someone still has to own what got generated. Ask the ops team whose non-technical COO vibe-coded a dashboard in a single HTML file and handed it over to “review and maintain” (r/sysadmin).
The problem isn’t AI. It’s the job AI was given. Automating dashboard-building means automating a job that shouldn’t exist.
We use AI too, just not to build dashboards. When every metric already arrives structured (node, instance, context, dimension, labels), charted, and with ML-detected anomalies attached, AI doesn’t have to guess what your data means. It can skip the panel-drawing and do the work you actually want at 3 a.m.: Netdata AI investigates the incident across your whole infrastructure and tells you what changed.
The industry knows
You don’t have to believe me. Read their own documentation:
Grafana’s best-practices doc defines “dashboard sprawl” as the uncontrolled growth of dashboards, grades the chaotic state “Low, default state: almost everyone starts here”, and describes the cure (reviews, approved lists, scripting libraries, “no editing in the browser”) as a maturity model whose final level is… doing it harder. Their own KubeCon talk is titled “Fool-Proof Kubernetes Dashboards for Sleep-Deprived Oncalls”. Datadog’s getting-started guide admits dashboards “often start as a scratch pad” and “gradually build”, which means you discover what to graph during the outage. Splunk’s built-in dashboards are “read-only”: to change one, “you need to clone the original dashboard and modify the cloned dashboard”. Customize one and you’re maintaining a fork.
And in December 2025, Grafana shipped “Suggested dashboards”, “designed to reduce the time it takes for you to create your first effective dashboard”. When the market leader starts cutting the price of dashboard building, that’s a confession: the price was always too high.
Five vendors have put the query-language barrier in writing: Chronosphere (“PromQL’s High Barrier of Entry… a burden for many engineers”), Splunk (“Flatten the SPL Learning Curve”), New Relic (“no NRQL knowledge required”), Grafana Drilldown (“no queries or complicated syntax required”), Honeycomb (“no advanced query language”). They sell you an AI to pay the toll faster.
They automate the catalog. Netdata automates the system.
But does it cover my stack?
Yes. That was the whole point of the five questions: they attach to every metric, from anywhere.
- 800+ integrations, auto-discovered, zero config: Linux, Windows, macOS, Kubernetes, containers, VMs, SNMP devices, Postgres, MySQL, Redis, Kafka, nginx, and on and on. See a live one: our network monitoring dashboard.
- The entire Prometheus ecosystem: any exporter, any
/metricsendpoint. If we don’t ship a profile for it, autogeneration already charts every scraped metric; a declarative profile upgrades it to a designed dashboard menu. The profile file is exactly those five decisions, written down once. - OpenTelemetry: the Agent is a native OTLP/gRPC receiver for metrics, logs, and traces — metrics become charts, logs and traces are stored and indexed on the node.
- Nagios: run your existing 4,000+ Nagios plugins unmodified, and your checks become charts and alerts.
- StatsD from any app, synthetic checks, a generic SQL collector for anything with a database driver, and an external plugin protocol for everything else, in any language.
Every metric that arrives answers the five questions (automatically for the 800+ we know, declaratively for everything else) and joins the same algorithmic dashboard, sliceable the same way.
And when you really do want a custom view, a specific lens for a specific war room, build it — custom dashboards exist. They are an optional layer on top of a complete default, not a substitute for one. And they aren’t forks: a custom dashboard references a context and its filters, then overrides only how it looks. When the collector improves, your custom view improves with it. When a new node matches the filter, it’s already there. That is the difference between “we couldn’t be bothered to build your dashboards” and “your dashboards were never supposed to be your job”.
The point
The question “who built this dashboard, and are they still here?” should be nonsense. The honest answer should be: nobody on your team. It came with the machine, designed once by people who still maintain it.
The industry turned dashboarding into a job, then sold you governance for the job, then sold you AI to do the job faster. We deleted the job.
You already bought the servers. Stop building their dashboard.
Get Netdata: one command, 60 seconds to first dashboard, zero dashboards to build. Yes, that number is ours. Check it.